A list of integer pairs is given. Each pair contains a first value and a second value. Rearrange the complete list in non-decreasing order of second values.
For pairs having equal second values, ordering by first values can be used to keep the final result deterministic. Return the sorted list of pairs.
Example 1
Input: pairs = [[1, 5], [2, 3], [4, 1], [3, 3]]
Output: [[4, 1], [2, 3], [3, 3], [1, 5]]
Explanation: Second values are 5, 3, 1, and 3. Sorting by second values gives order 1, 3, 3, and 5. Equal second values 3 are arranged by first values, so [2, 3] appears before [3, 3].
Example 2
Input: pairs = [[8, 2]]
Output: [[8, 2]]
Explanation: A single pair already satisfies sorted order, so no rearrangement is required.
Brute Force Approach
The easiest way to sort pairs by second value is to repeatedly place the smallest remaining second value at the next open position. The first value travels together with the second value, so every pair stays intact during swaps.
During each pass, the unsorted suffix is scanned completely. The pair with the smallest second value is selected. When two second values are equal, the smaller first value is preferred so the output remains predictable.
The idea feels close to arranging cards by a printed score. One complete scan chooses the next best card, then the boundary moves forward by one position.
Algorithm
The number of pairs is stored in
nso every boundary position can be processed.Every boundary from
0throughn - 2is treated as the next position needing the correct pair.An index named
minIndexis initialized with the boundary because the boundary pair is the first candidate for the smallest second value.The remaining suffix is scanned from
boundary + 1throughn - 1so every unplaced pair can be compared.minIndexis updated when a smaller second value is found, or when equal second values have a smaller first value.The selected pair is swapped with the boundary pair after the scan, so the sorted prefix grows by one pair.
The sorted list is returned after every required boundary has been processed.
Dry Run
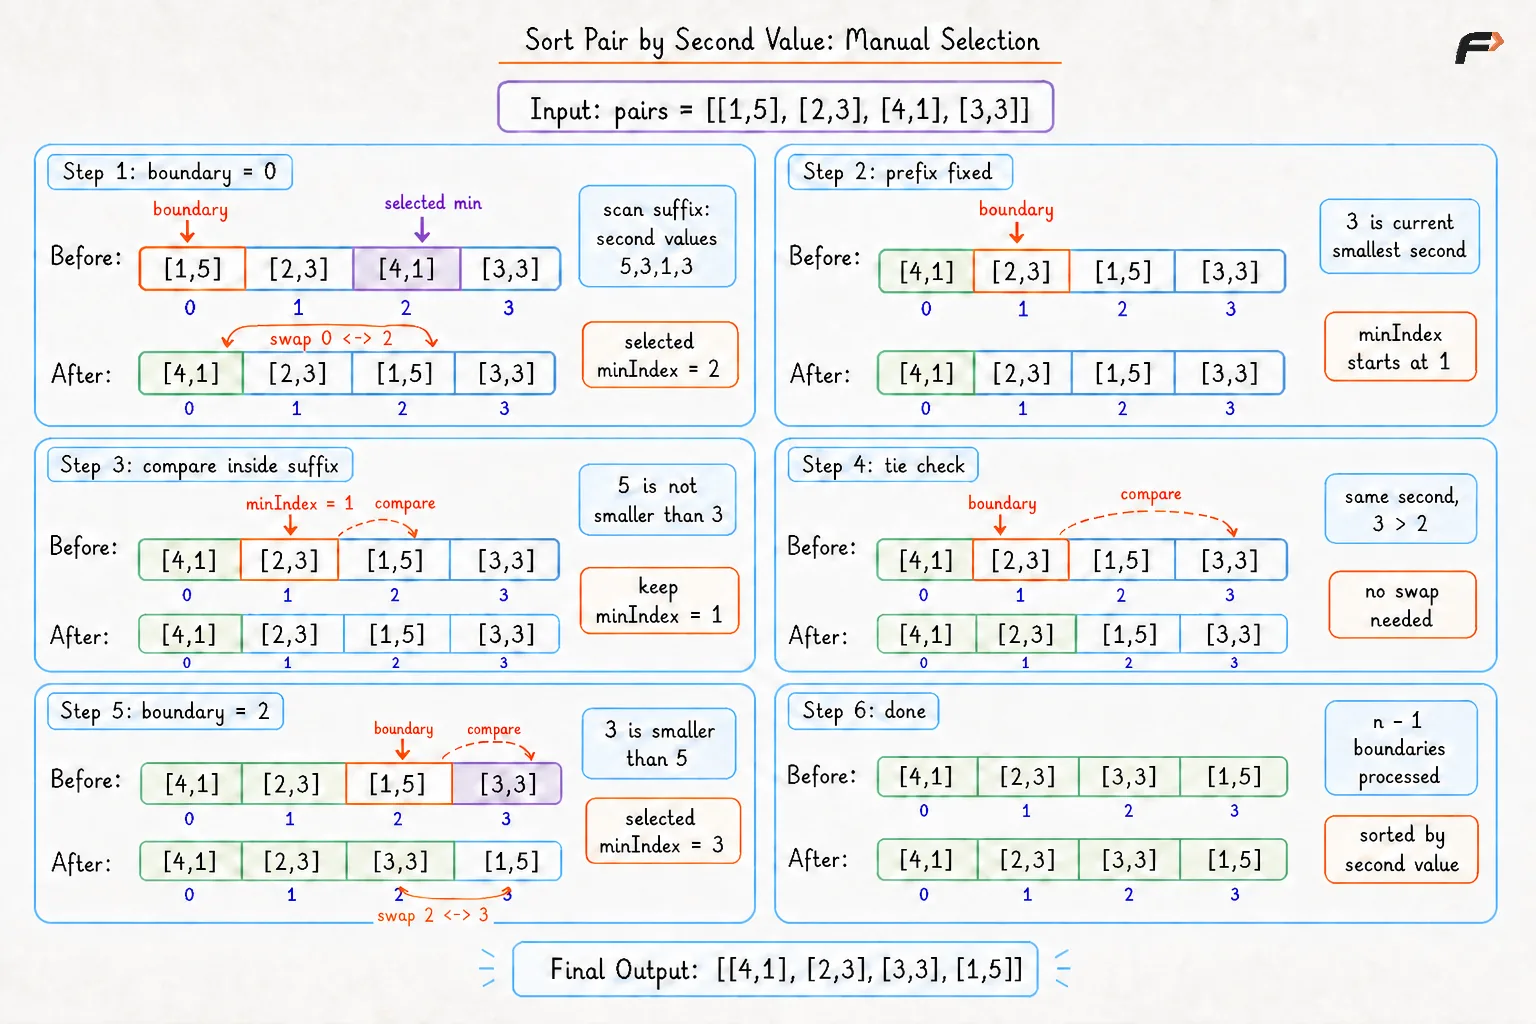
Sort Pair by second Value Brute Approach
Solution
#include <bits/stdc++.h>using namespace std;class Solution {public: // Function sorts pairs by second value using repeated selection. vector<pair<int, int>> sortPairsBySecond(vector<pair<int, int>> pairs) { int n = pairs.size(); // Each boundary marks the next sorted position. for (int boundary = 0; boundary < n - 1; boundary++) { int minIndex = boundary; // Remaining pairs are scanned to find the best candidate. for (int index = boundary + 1; index < n; index++) { bool hasSmallerSecond = pairs[index].second < pairs[minIndex].second; bool hasEqualSecond = pairs[index].second == pairs[minIndex].second; bool hasSmallerFirst = pairs[index].first < pairs[minIndex].first; // The candidate changes when second value is smaller or tie is improved. if (hasSmallerSecond || (hasEqualSecond && hasSmallerFirst)) { minIndex = index; } } // A swap is useful only when a different pair was selected. if (minIndex != boundary) { swap(pairs[boundary], pairs[minIndex]); } } return pairs; }};// Driver codeint main() { // Input array vector<pair<int, int>> pairs = {{1, 5}, {2, 3}, {4, 1}, {3, 3}}; // Solution object creation Solution obj; // Result printing vector<pair<int, int>> result = obj.sortPairsBySecond(pairs); for (int index = 0; index < result.size(); index++) { cout << "[" << result[index].first << ", " << result[index].second << "]"; // A separator is printed only between neighboring pairs. if (index + 1 < result.size()) { cout << " "; } } return 0;}Complexity Analysis
Time Complexity: O(N2), where N is the number of elements in the array, because each boundary position scans the remaining unsorted suffix. The number of comparisons is (N - 1) + (N - 2) + ... + 1.
Space Complexity: O(N), because a copied output list is stored in Python, Java, and JavaScript. C++ receives the list by value and rearranges the copied list.
Better Approach
Repeated suffix scans make manual selection quadratic. Merge sort avoids repeated full scans by dividing the pair list into smaller halves, sorting both halves, and joining both sorted halves in linear time.
During every merge, the smaller second value moves first. Equal second values use the smaller first value directly inside the merge condition. Pair fields stay together during every move, and no sorting-library comparison callback is needed.
Algorithm
Begin with a copied pair list and a temporary list of equal size, so merging can rearrange pairs without losing any value.
Start merge sort on the complete index range because every pair belongs to the final sorted order.
Stop a recursive call at a range containing at most one pair because such a range already satisfies the required order.
Split every larger range at the middle index and sort both halves recursively, so the merge step receives two sorted ranges.
Compare the current pair from each half by second value first and by first value after an equal second value, so the exact ordering rule is applied directly.
Move the smaller pair into the temporary list and copy every leftover pair after one half finishes, so no pair is skipped during merging.
Copy the merged range back into the pair list, so every completed range can support the next merge, and return the list after the full range becomes sorted.
Dry Run
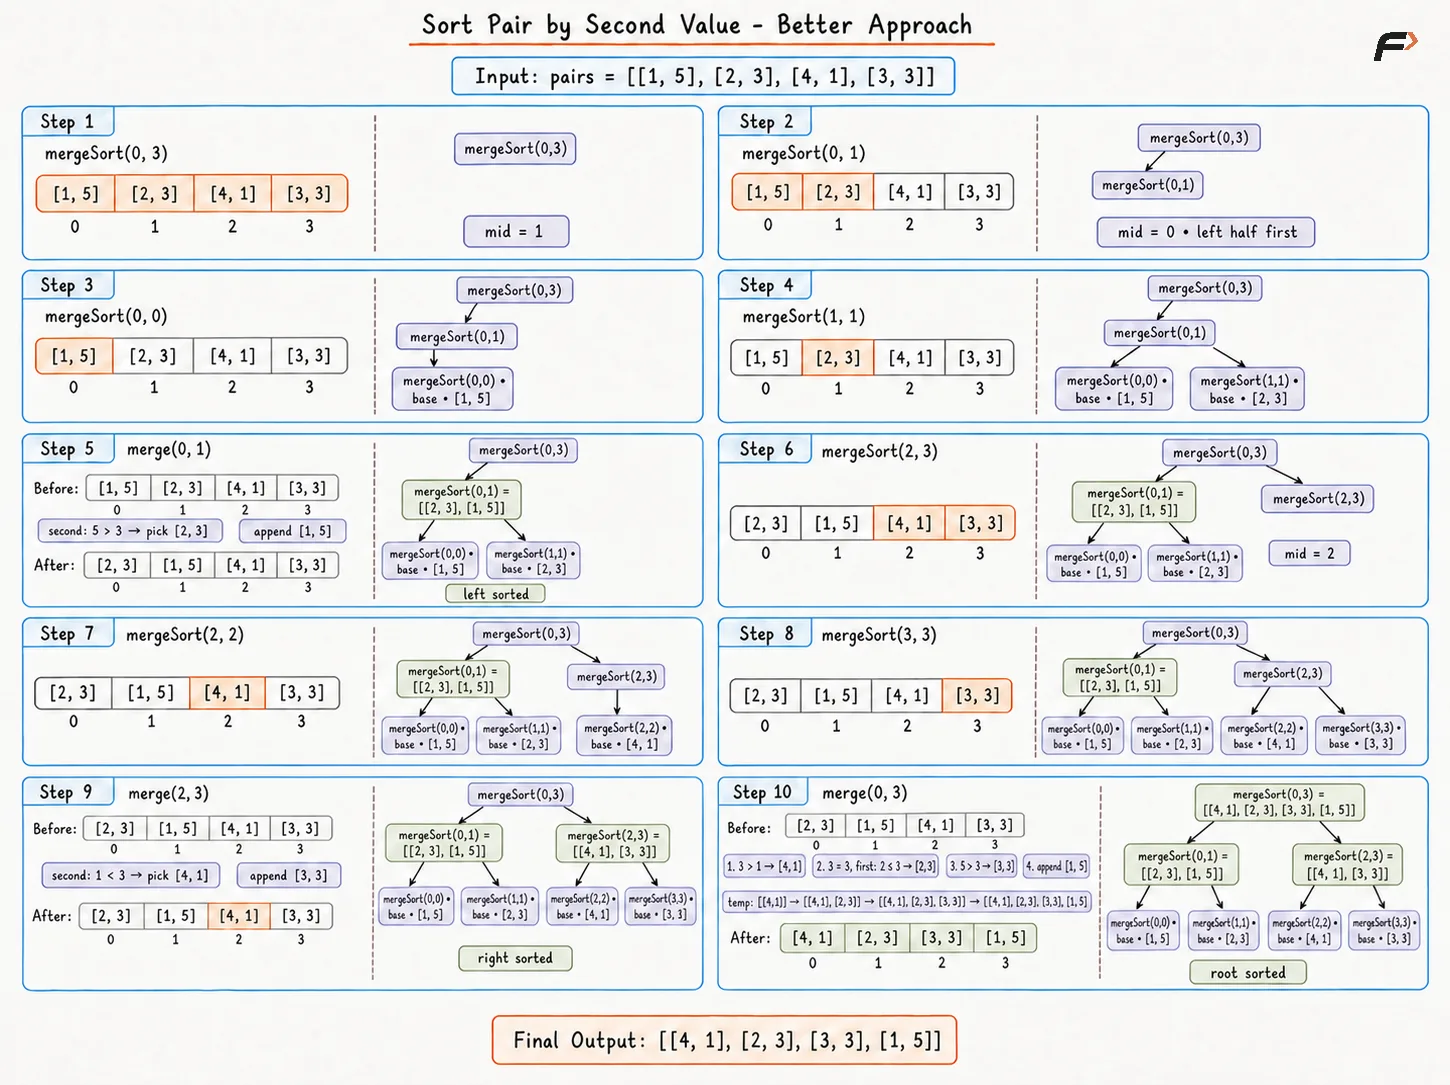
sort-pair-by-second-value-better-approach
Solution
#include <bits/stdc++.h>using namespace std;class Solution {private: // Function merges two sorted pair ranges. void mergeRanges(vector<pair<int, int>>& pairs, vector<pair<int, int>>& temp, int left, int middle, int right) { int leftIndex = left; int rightIndex = middle + 1; int writeIndex = left; // Current pairs provide the next smallest value. while (leftIndex <= middle && rightIndex <= right) { // Direct field checks choose the earlier pair. if (pairs[leftIndex].second < pairs[rightIndex].second || (pairs[leftIndex].second == pairs[rightIndex].second && pairs[leftIndex].first <= pairs[rightIndex].first)) { temp[writeIndex] = pairs[leftIndex]; leftIndex++; } else { temp[writeIndex] = pairs[rightIndex]; rightIndex++; } writeIndex++; } // Remaining left pairs keep sorted order. while (leftIndex <= middle) { temp[writeIndex] = pairs[leftIndex]; leftIndex++; writeIndex++; } // Remaining right pairs keep sorted order. while (rightIndex <= right) { temp[writeIndex] = pairs[rightIndex]; rightIndex++; writeIndex++; } // The merged range replaces the old range. for (int index = left; index <= right; index++) { pairs[index] = temp[index]; } } // Function sorts one pair range with merge sort. void mergeSort(vector<pair<int, int>>& pairs, vector<pair<int, int>>& temp, int left, int right) { // A one-pair range already has sorted order. if (left >= right) { return; } int middle = left + (right - left) / 2; // Both halves become sorted before merging. mergeSort(pairs, temp, left, middle); mergeSort(pairs, temp, middle + 1, right); // Two sorted halves form one sorted range. mergeRanges(pairs, temp, left, middle, right); }public: // Function sorts pairs using direct merge sort. vector<pair<int, int>> sortPairsBySecond( vector<pair<int, int>> pairs) { int n = pairs.size(); vector<pair<int, int>> temp(n); // A larger list needs recursive splitting. if (n > 1) { mergeSort(pairs, temp, 0, n - 1); } return pairs; }};// Driver codeint main() { vector<pair<int, int>> pairs = { {1, 5}, {2, 3}, {4, 1}, {3, 3} }; Solution obj; vector<pair<int, int>> result = obj.sortPairsBySecond(pairs); for (int index = 0; index < result.size(); index++) { cout << "[" << result[index].first << ", " << result[index].second << "] "; } cout << "\n"; return 0;}Complexity Analysis
Time Complexity: O(N log N), because merge sort performs O(log N) division levels and merges all N pairs once per level.
Space Complexity: O(N), because the temporary list stores n pairs while the recursion stack uses O(log N) additional space.
Optimal Approach
Manual selection teaches the comparison rule clearly, but repeated full scans are costly. Sorting libraries already implement faster comparison sorting, so the main work becomes describing the correct ordering rule.
The comparator checks second values first. A pair with a smaller second value must come earlier. Equal second values are settled by first values only to keep the result deterministic.
The heart of the solution is pleasantly small: keep every pair as one unit, and give the sorting routine a rule for choosing the earlier pair.
Algorithm
A copy of the pair list is created so the original input can stay unchanged.
A comparator or sorting key is prepared to compare pairs by second value first.
First values are used only when second values are equal, so a deterministic order is produced.
The language sorting routine is applied to the copied list using the custom comparison rule.
During sorting, pair positions are rearranged while pair contents remain together.
The sorted list is returned after the library routine finishes.
Dry Run
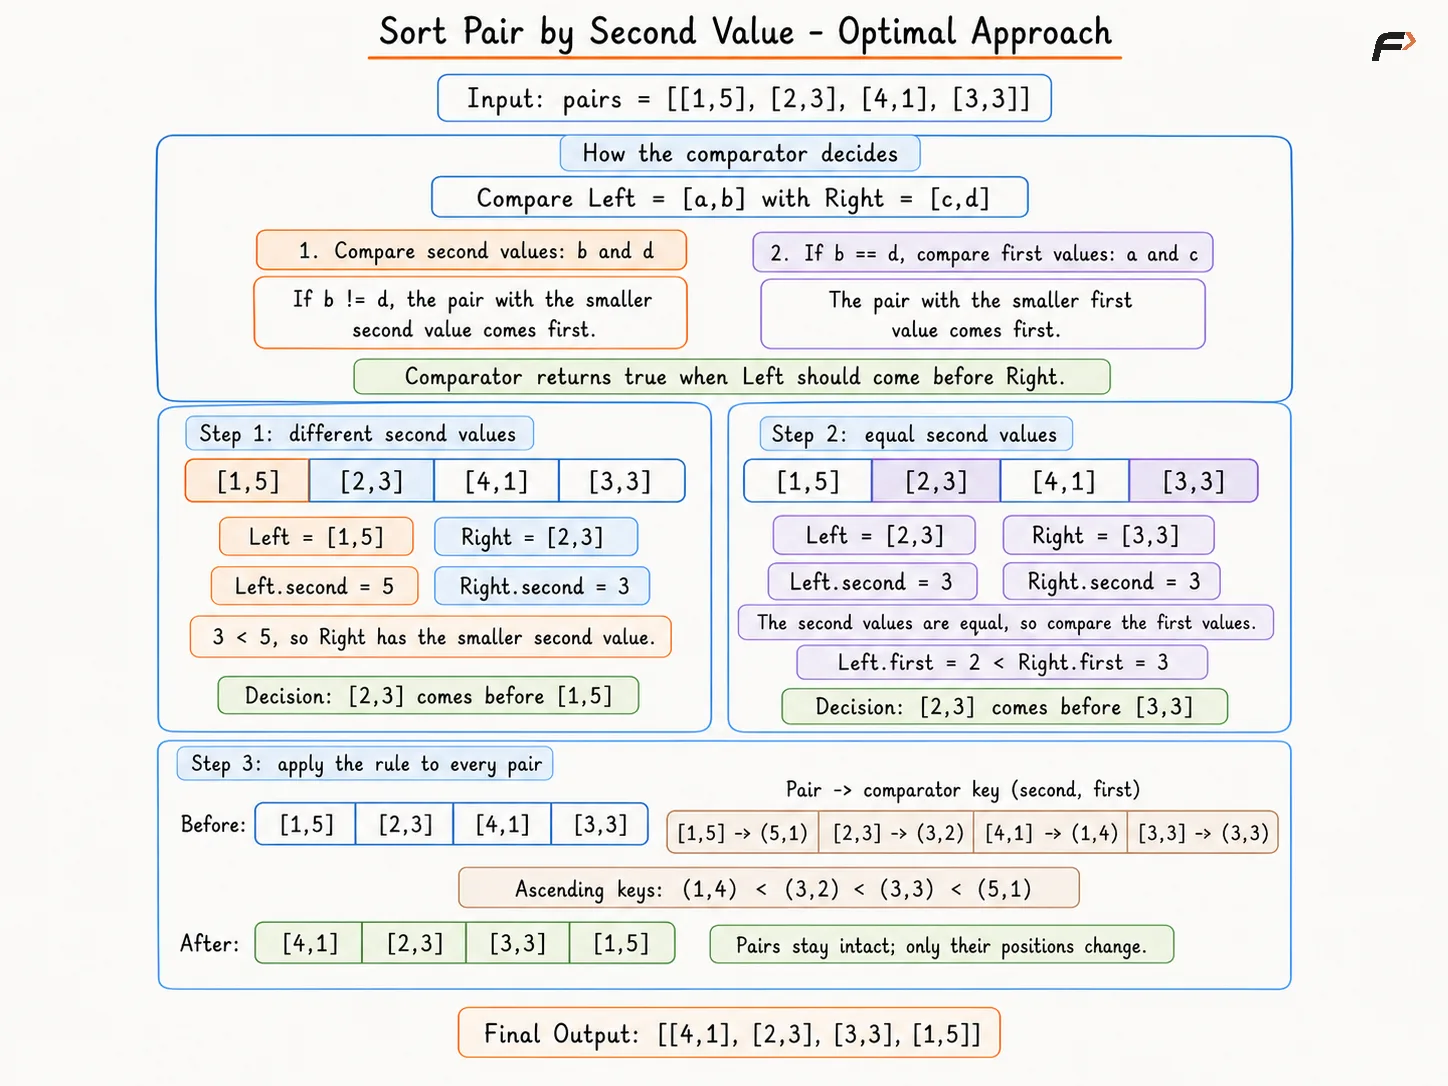
Image 1
Solution
#include <bits/stdc++.h>using namespace std;class Solution {public: // Function sorts pairs by second value using a custom comparator. vector<pair<int, int>> sortPairsBySecond(vector<pair<int, int>> pairs) { sort(pairs.begin(), pairs.end(), [](pair<int, int> left, pair<int, int> right) { // Equal second values are ordered by first value for deterministic output. if (left.second == right.second) { return left.first < right.first; } return left.second < right.second; }); return pairs; }};// Driver codeint main() { // Input array vector<pair<int, int>> pairs = {{1, 5}, {2, 3}, {4, 1}, {3, 3}}; // Solution object creation Solution obj; // Result printing vector<pair<int, int>> result = obj.sortPairsBySecond(pairs); for (int index = 0; index < result.size(); index++) { cout << "[" << result[index].first << ", " << result[index].second << "]"; // A separator is printed only between neighboring pairs. if (index + 1 < result.size()) { cout << " "; } } return 0;}Complexity Analysis
Time Complexity: O(N log N), because the built-in sorting routine performs comparison sorting over N pairs.
Space Complexity: O(N), because a copied result list is stored before sorting. Extra internal sorting space depends on the language runtime, but the copied list dominates the auxiliary storage used by the shown code.
Interview follow-up Questions
Yes. Equal second values can appear. A tie-breaker based on first values keeps the final order deterministic, although many platforms accept any order among equal second values when no tie rule is specified.
Be the first to add a comment.