1. Basic Pattern Matching Problem
Suppose a word needs to be searched inside a larger sentence or string. The goal is to find all starting positions where the smaller pattern exactly matches a part of the text.
The useful observation is that every match must occupy a continuous block of length equal to the pattern. So the pattern can be aligned at different positions in the text and checked against the corresponding characters.
Key Points
If the pattern length is greater than the text length, no match is possible.
Matching is usually case-sensitive unless the problem says otherwise.
Overlapping matches are valid in many DSA problems, such as finding
"aa"in"aaaa".
Example 1
Input: text = "abcabcabc", pattern = "abc"
Output: 0, 3, 6
Explanation: The pattern starts at indices 0, 3, and 6.
Example 2
Input: text = "hello", pattern = "ll"
Output: 2
Explanation: The pattern "ll" starts at index 2.
Algorithm
Check whether the pattern is empty or longer than the text, because these cases need direct handling.
Place the pattern at each possible starting index in the text.
Compare the pattern characters with the text characters from left to right.
If all characters match, record the current starting index.
Continue until every possible starting index has been checked.
Return all recorded match positions.
Dry Run
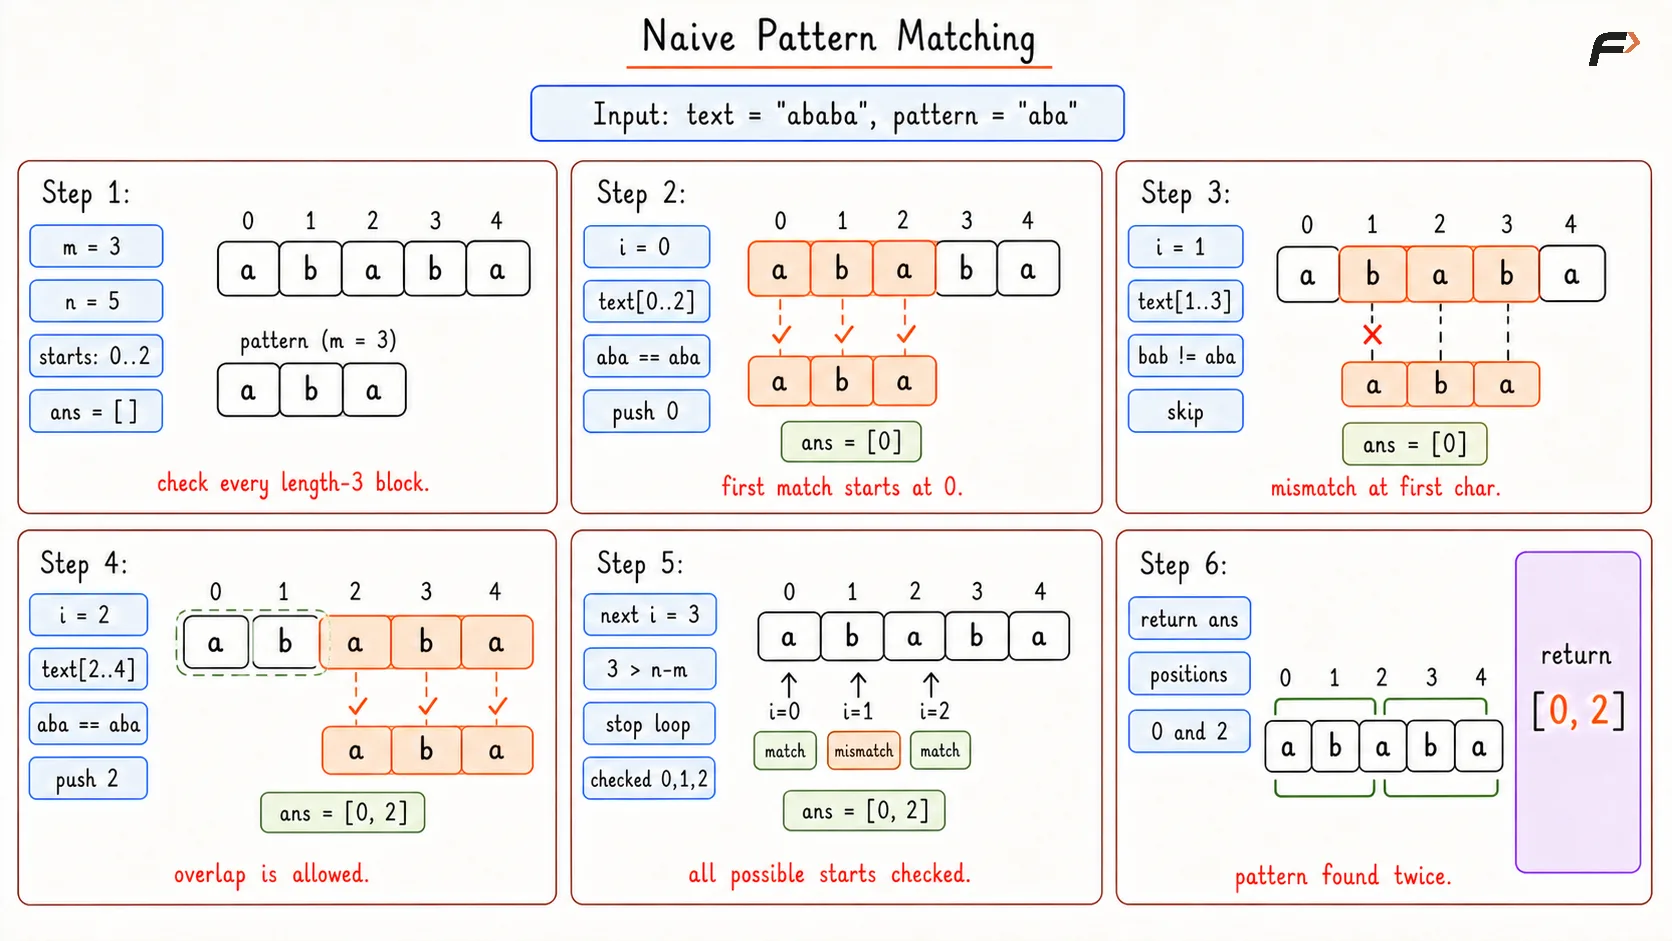
Pattern Matching in String
Complexity Analysis
Time Complexity: O(n * m), where n is the text length and m is the pattern length, because each starting position may compare up to m characters.
Space Complexity: O(1), excluding the answer list, because only a few variables are needed.
2. KMP Algorithm
Sometimes a pattern has repeated parts, such as "abab" or "abcab". If a mismatch happens after several characters have already matched, restarting from the next text index wastes information.
The KMP algorithm uses the idea of longest prefix which is also a suffix. This helps decide how much of the pattern can still be reused after a mismatch, so matched characters are not checked again unnecessarily.
Key Points
KMP uses an LPS array, also called a prefix table.
LPS means longest proper prefix that is also a suffix.
KMP is especially useful when the pattern contains repeated structure.
It gives guaranteed linear time.
Example 1
Input: text = "ababcabc", pattern = "abc"
Output: 2, 5
Explanation: The pattern "abc" appears at indices 2 and 5.
Example 2
Input: text = "aaaaa", pattern = "aa"
Output: 0, 1, 2, 3
Explanation: Overlapping matches are found without restarting from scratch each time.
Algorithm
Build the LPS array for the pattern so repeated prefix-suffix information is available.
Start scanning the text and pattern from the beginning.
If characters match, move both pointers forward.
If a mismatch happens after some pattern characters matched, use the LPS value to move the pattern pointer.
If a mismatch happens at the first pattern character, move to the next text character.
When the full pattern is matched, record the starting index and continue using the LPS value.
Dry Run
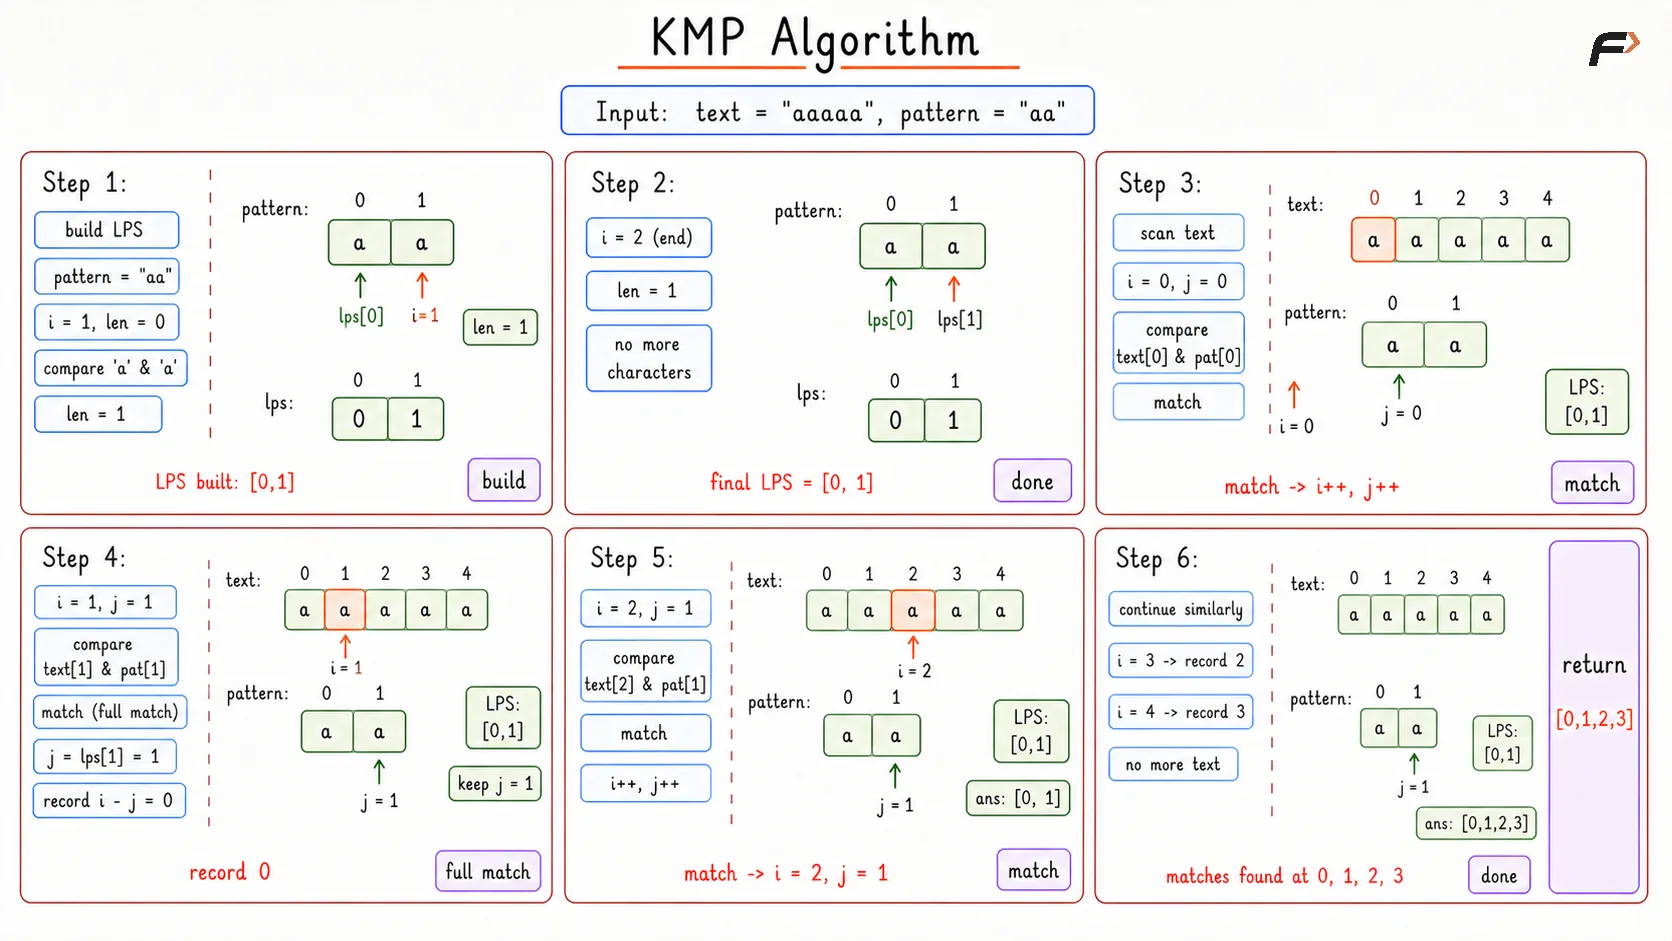
Kmp Intro Dry Run
Complexity Analysis
Time Complexity: O(n + m), because the LPS array is built once and the text is scanned once.
Space Complexity: O(m), because the LPS array stores information for the pattern.
3. Rabin-Karp Algorithm
Instead of comparing every character directly, a pattern can be converted into a number-like value called a hash. Each text window of the same length can also be hashed and compared with the pattern hash.
The main trick is the rolling hash. When the window moves by one position, the old hash can be updated quickly instead of recalculating the whole window from scratch.
Key Points
Rabin-Karp is useful for multiple pattern search and plagiarism-style matching.
Hash collisions can happen, where two different strings produce the same hash.
A character-by-character check is still needed when hashes match.
Average performance is fast, but poor hashing can create extra checks.
Example 1
Input: text = "abcdabc", pattern = "abc"
Output: 0, 4
Explanation: Windows at indices 0 and 4 match the pattern.
Example 2
Input: text = "banana", pattern = "ana"
Output: 1, 3
Explanation: The pattern appears twice, including an overlapping match.
Algorithm
Calculate the hash value of the pattern.
Calculate the hash value of the first text window of pattern length.
Compare the pattern hash with the current window hash.
If the hashes match, verify the actual characters to avoid false matches due to collision.
Slide the window by one character and update the hash using the rolling hash idea.
Continue until all windows are checked.
Dry Run
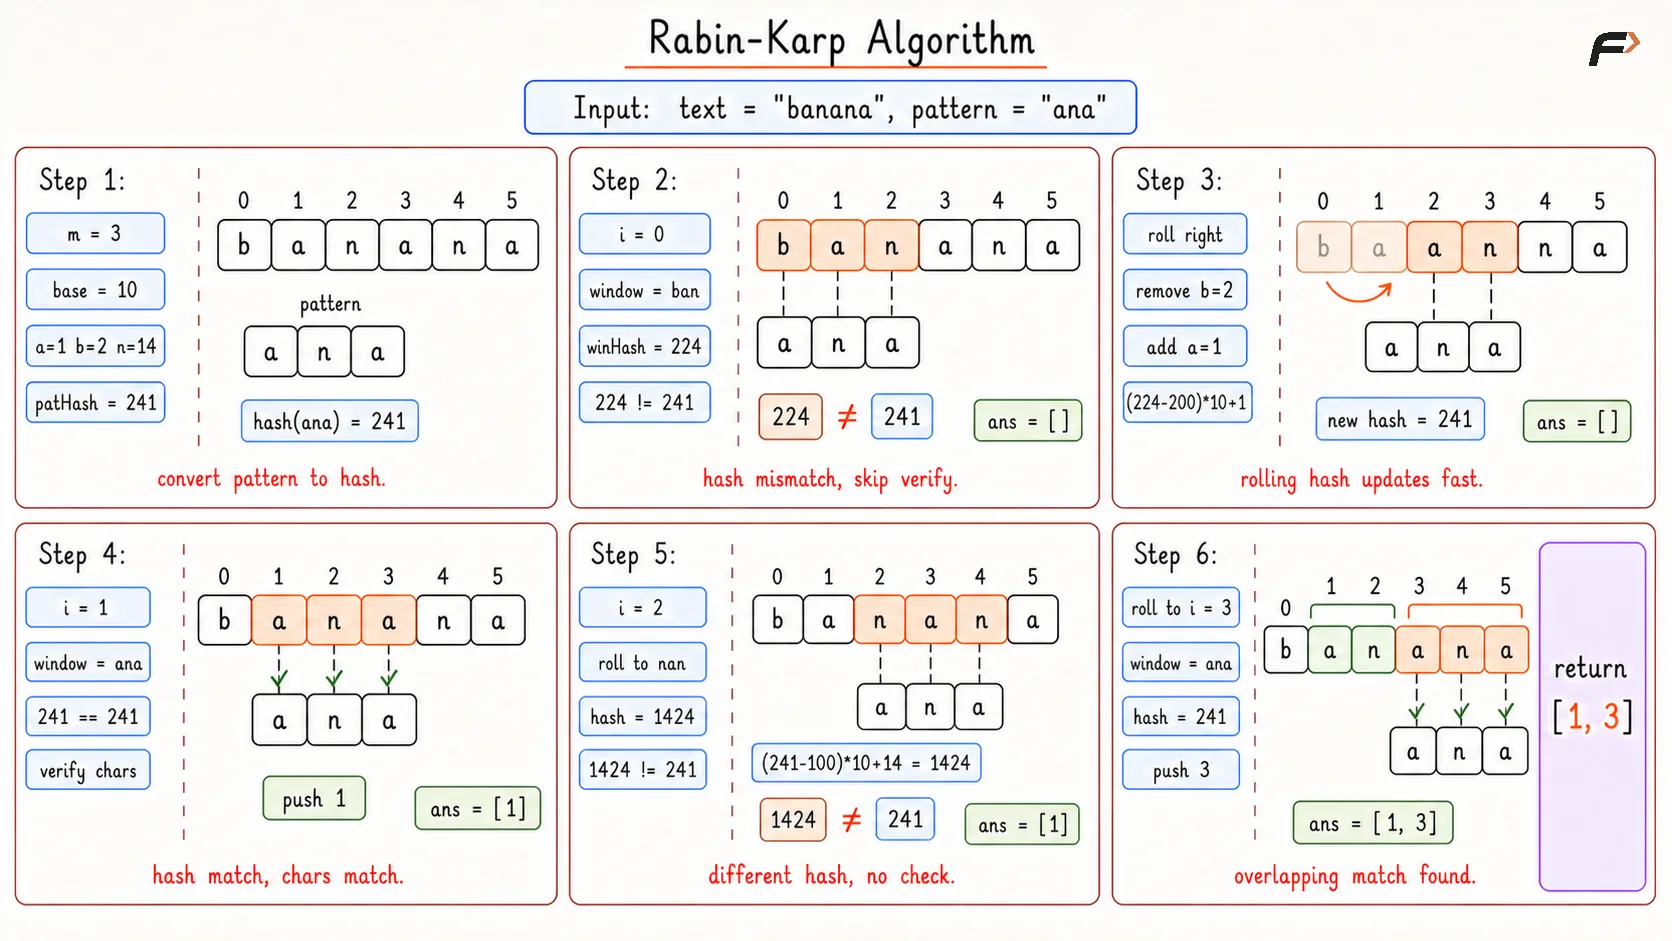
Rabin Carp Algorithm
Complexity Analysis
Time Complexity: O(n + m) on average, because rolling hash makes each window update fast. In the worst case, collisions may cause O(n * m).
Space Complexity: O(1), excluding the answer list, because only hash values and counters are stored.
Be the first to add a comment.